The Context: I recently ran a repair pass on a mesh and got an interesting result:
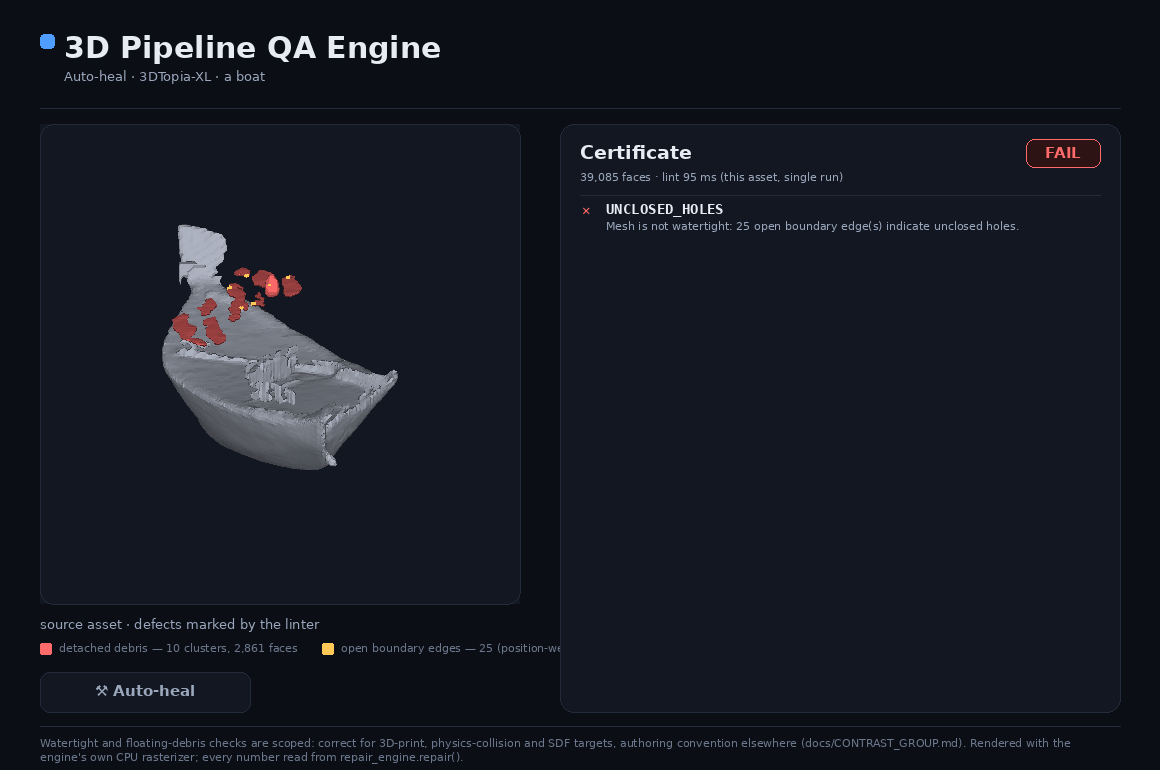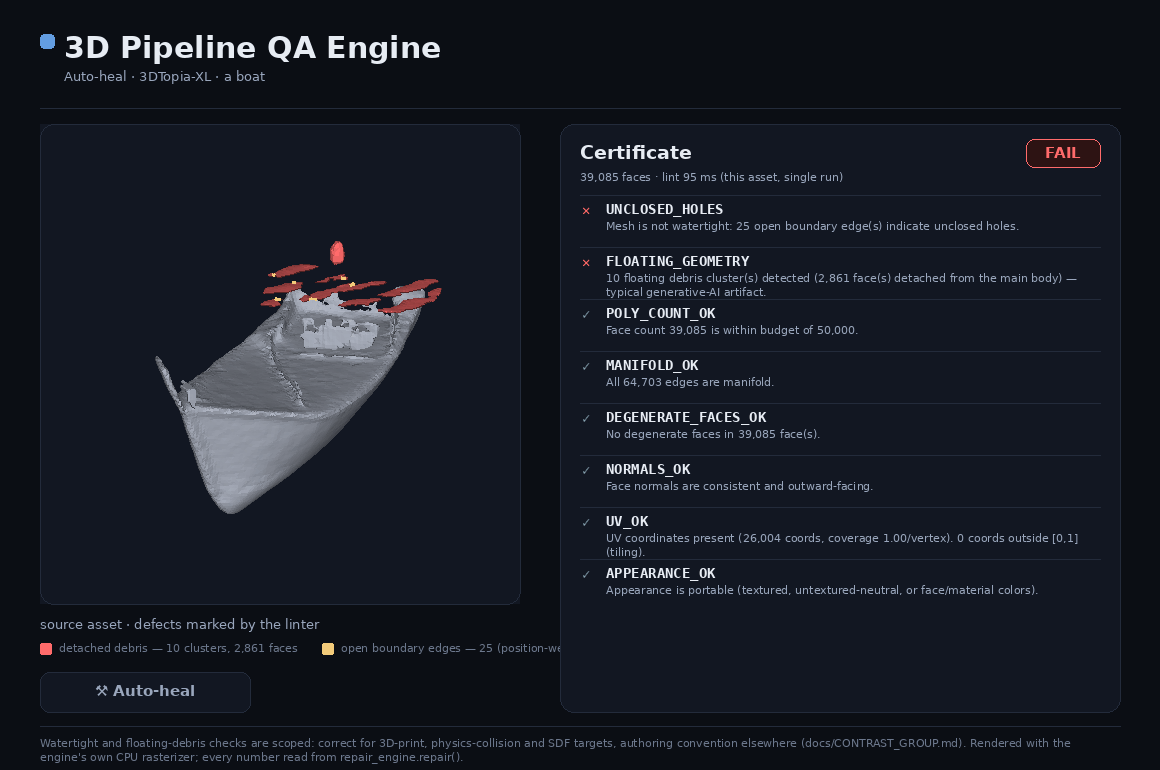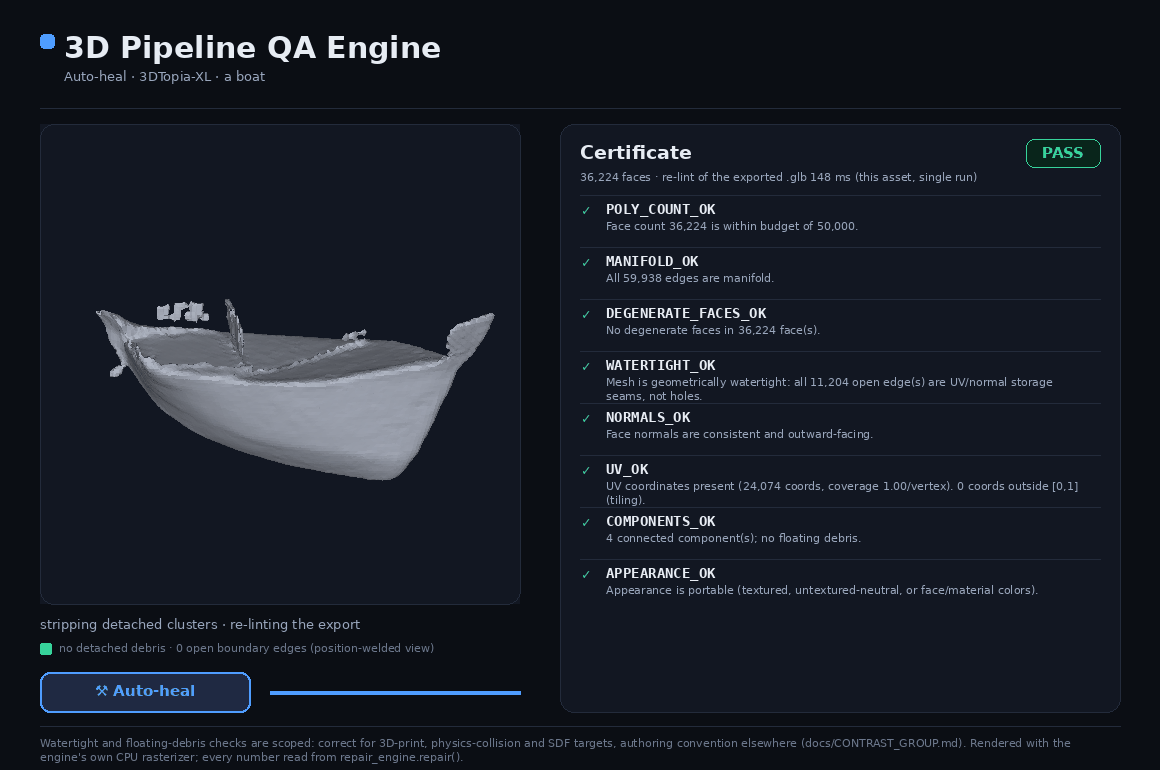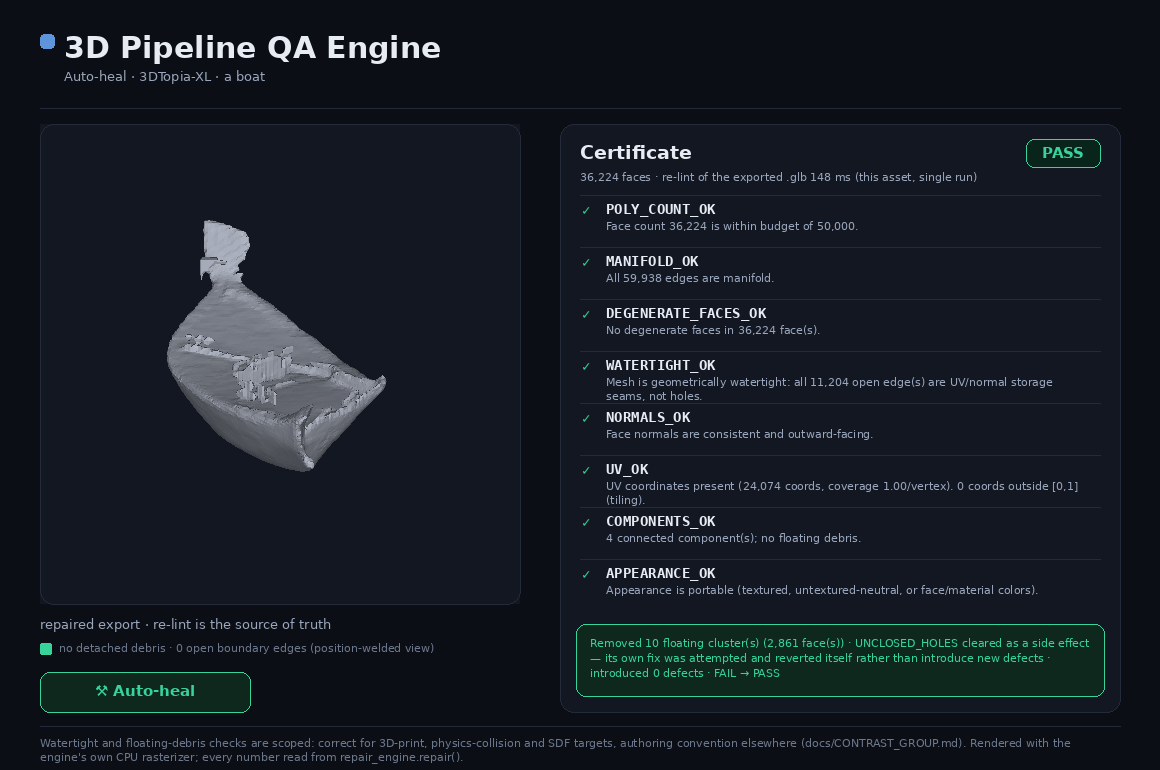
10 detached clusters (2,861 faces) floating above the hull, marked in red by the detector, the same tool meant to delete them.
Repair stripped the debris, leaving the mesh completely watertight.
Catch: It wasn’t watertight because the hole-fill succeeded. The fill was attempted, but because it would have introduced 336 non-manifold edges, it reverted itself.
All 25 open boundary edges just happened to live on the floating debris that got removed.
The tool ended up reporting the mesh as watertight on its own output report without claiming credit for “fixing” the holes. The side effect did the heavy lifting.
Our mesh QA tools alert errors and identifies offending geo, but only automatically fixes the most bullet proof, stupid, easy issues. Anything requiring human judgement or prone to weird edge cases is passed back to the modeler. I don’t think Gen AI is up to it.
“Only auto-fix the bulletproof cases, pass the rest back” is where I landed too, from the other direction. Useful to hear it from someone shipping.
The one thing I’d like your read on: which of those two buckets does a measurable cost fall into? Before it commits to anything, the engine knows how many non-manifold edges a hole fill would create. That isn’t human judgement and it isn’t a weird edge case, it’s a number I already have, and I can’t decide whether it should gate the fix automatically or just get printed beside the defect and left to the modeler. Noting you said yours identifies the offending geo, which mine mostly doesn’t, it emits counts, and a count is not a location.
On gen AI not being up to it, if you mean the judgement calls, agreed. If you mean the assets, my own numbers won’t tell the story I expected. Across 2,004 generated and 149 human-authored CC0 assets, faces over aspect ratio 20 come out at 0.240% generated against 1.529% authored, so the humans are 6.4x worse on average. Ranked by the worst sliver in each asset it flips: median max aspect 1,682 generated against 143 authored, 12x worse at the extreme. Sloppier on average, fails harder when it fails. I had a tidier narrative before I ran it.
I usually only work with skinned meshes, and nonmanifold is not allowed for those in our engine.
I’m not sure what the true perf cost of non-manifold geo on static meshes is for us. I know the static mesh modelers can get away with way more ‘bad geo’ than character modelers. And our render team has all kinds of black magic to optimize the heck out of, leveraging the fact that it is static.
The tool I speak of runs in Maya and creates selection sets of the offending geo so artists can easily find what needs attention
And yes, I don’t think AI is up to judgement calls and weird edge cases. I’m sure its capacity to generate geo within specified performance parameters is steadily improving.
In point of fact, my lead just shared tripod.ai with me. Gen AI image-to-game-mesh. I am impressed by the resulting topology, compared to similar image-to-mesh products form a year ago. But I only glanced at it, I have not seen multiple result models.
Your first line answers the thing I was stuck on and I did not see it at the time. I was asking which of your two buckets a measurable cost falls into: the engine knows how many non-manifold edges a hole fill would create before it commits, and that is neither human judgement nor a weird edge case, so I could not place it. But non-manifold not being allowed on skinned meshes in your engine is a threshold at zero, and on static meshes you said you do not know the true perf cost and your modelers get away with more. So the bucket is not a property of the check.
Which makes selection sets the other half. If the number gates, fine. If it prints, it has to print somewhere the artist can act on, and a count is not a location. Yours hands back the geo, mine hands back an integer. That is a real gap rather than a nitpick, and it is the next thing I build.
The generalisation is the part I do not have at all. Static prop, deforming character, modular equipment, environment asset: different standards for the same geometry, set by what the asset is for. Someone else asked for exactly that this week, keyed to asset role, arriving from the opposite direction. My profiles key off target platform, which is the wrong axis.
Since you had only glanced at a result: I have 198 Tripo models measured, one row per model. Non-manifold edges on 32.7% of the TripoSG models (33 of 101) and 14.4% of TripoSR (14 of 97). Welded topology matched storage topology on 198 of 198, so that is geometric rather than an artefact of how the file was written. None of it argues with your read on the topology, since flow and manifoldness are different properties and mine only measures the second one. But against your
own skinned rule, a third of one model line is a third you would bounce at the door for character work. Happy to hand the per-model table to your lead if it is any use, it is a CSV.
Appreciate the offer to share data. We are only evaluating tripo at the moment. But 32.7% and 14% occurrences for non-manifold geo is something to keep in mind, for sure.
One thing worth attaching to those two figures before they travel further: the median affected model carries four non-manifold edges, and TripoSG’s median mesh is about 1.37 million faces. So what those percentages describe is a handful of real edges per model, not a third of the output being unusable.
That cuts against my own case, and it says nothing either way about the topology you were impressed by, which I have no opinion on. But a rate without a magnitude reads worse than it is, and if the figure reaches your lead it should carry both.